Generative AI & visual learning
Learning to create and understand visual data
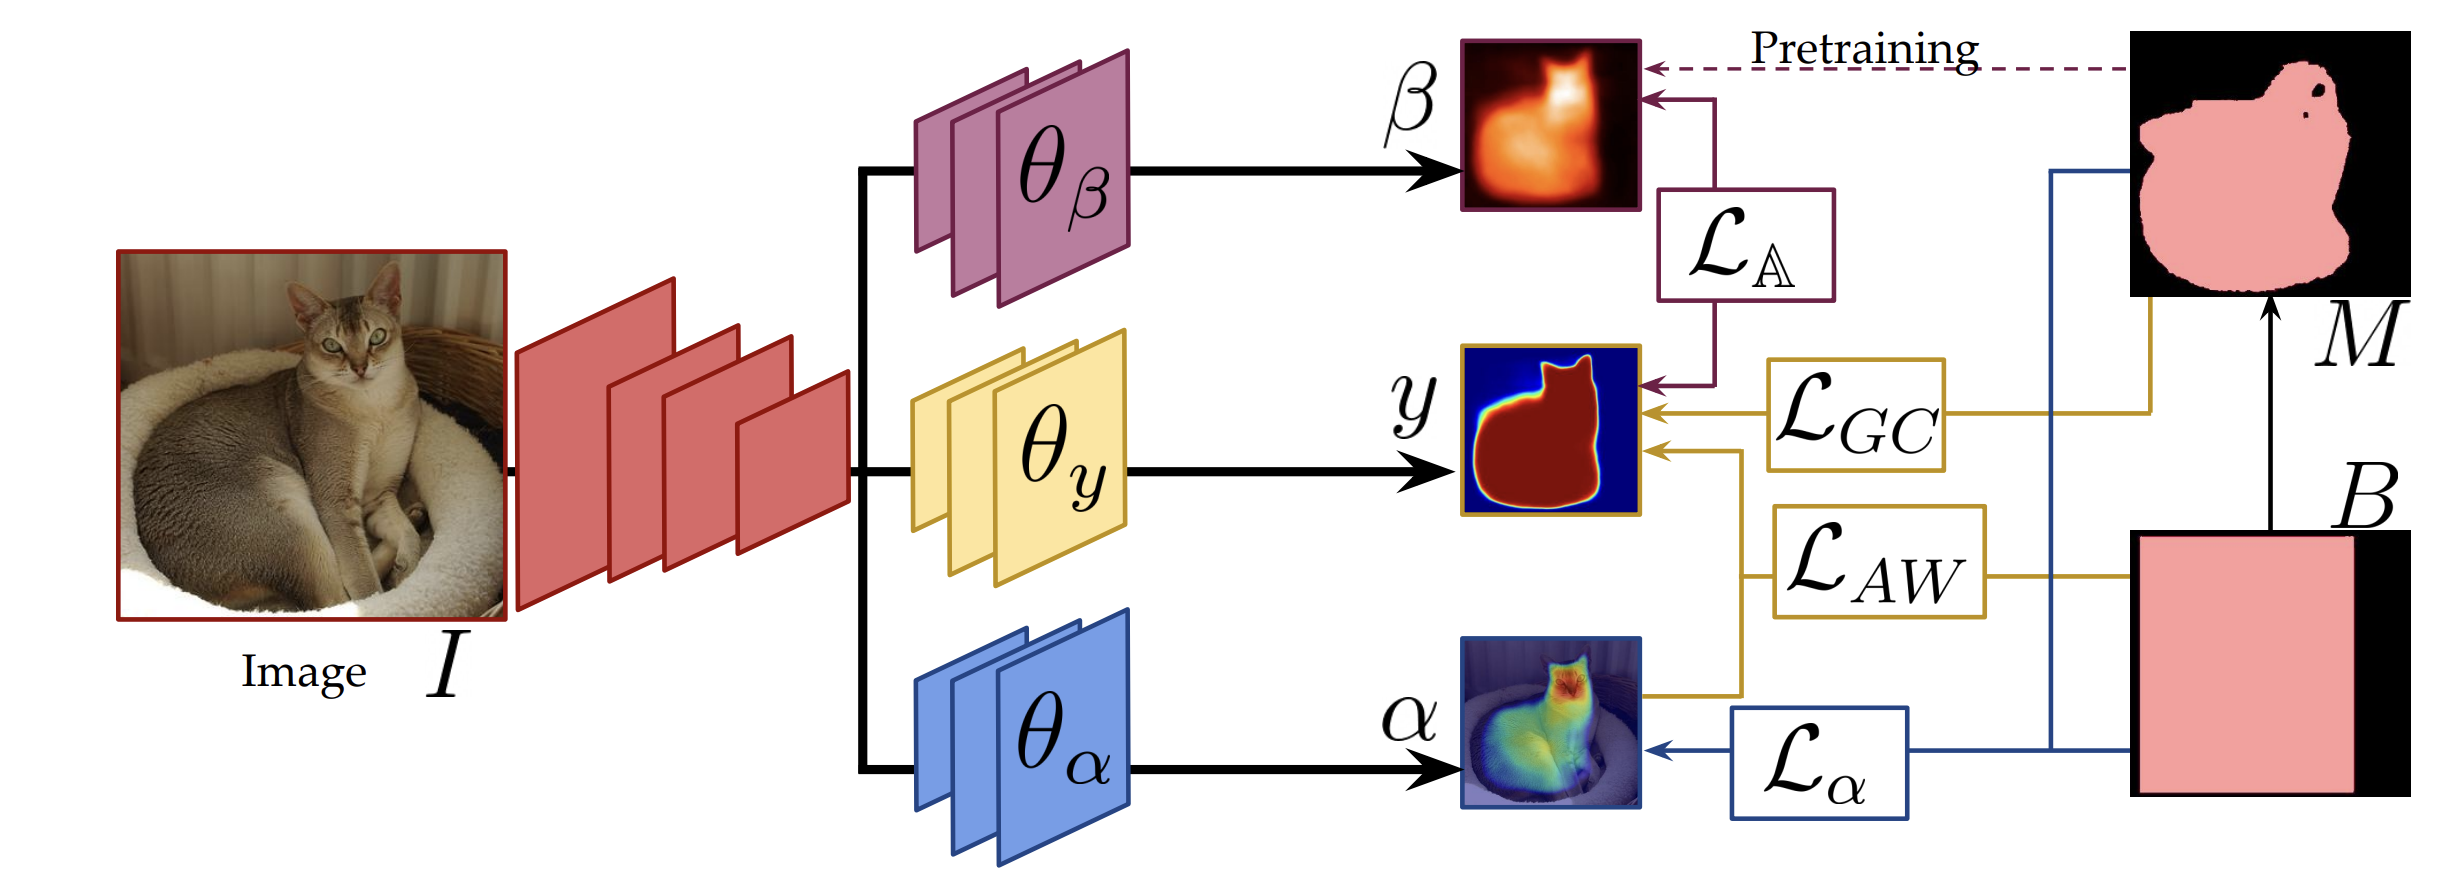
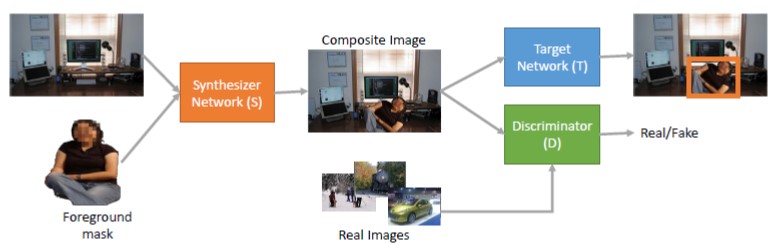
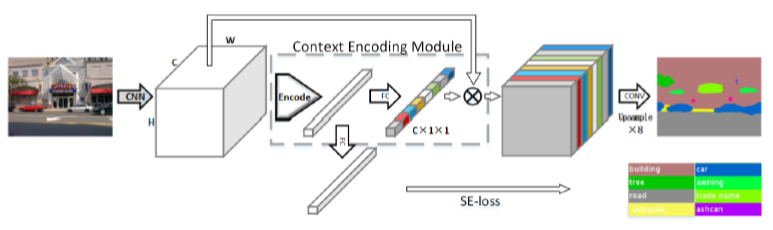
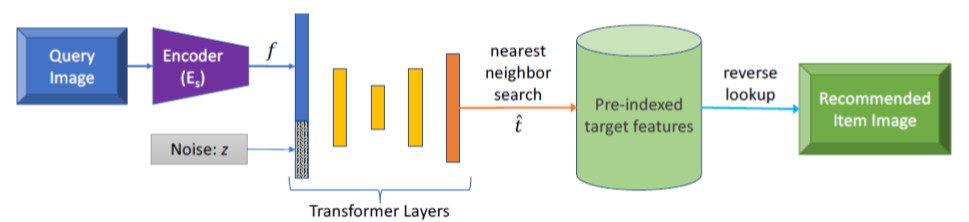
Research includes synthetic data generation, weakly supervised learning, semantic segmentation, and learned visual representations.
I am a Principal Scientist at Amazon with 20+ years of experience at the intersection of AI research, generative and multimodal models, computer vision, and computational photography. I transform advanced research into scalable products used by millions of customers worldwide. My work spans learned representations, 3D human understanding, camera geometry, and computational image formation, with 50+ U.S. patents and 55+ peer-reviewed publications in top-tier venues including CVPR, ICCV, ECCV, and SIGGRAPH. With 12,000+ citations and an h-index of 50, my research reflects a sustained record of innovation and impact. I thrive on bridging cutting-edge AI research with customer-focused product delivery, leading teams from concept to deployment.
Research includes synthetic data generation, weakly supervised learning, semantic segmentation, and learned visual representations.
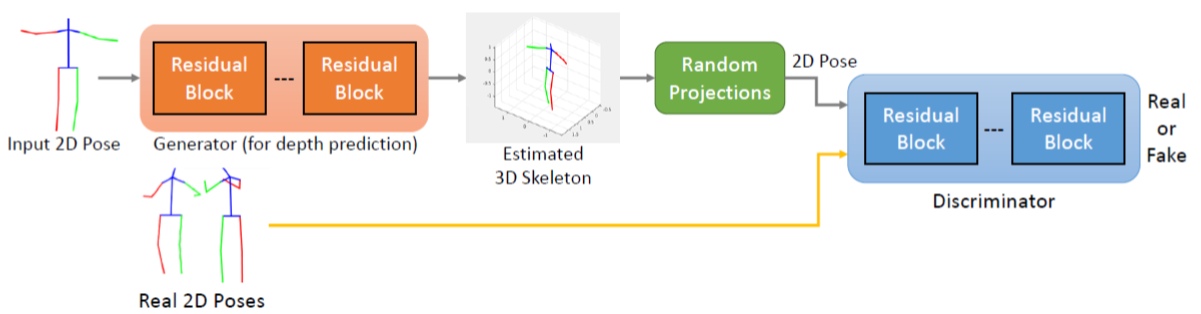
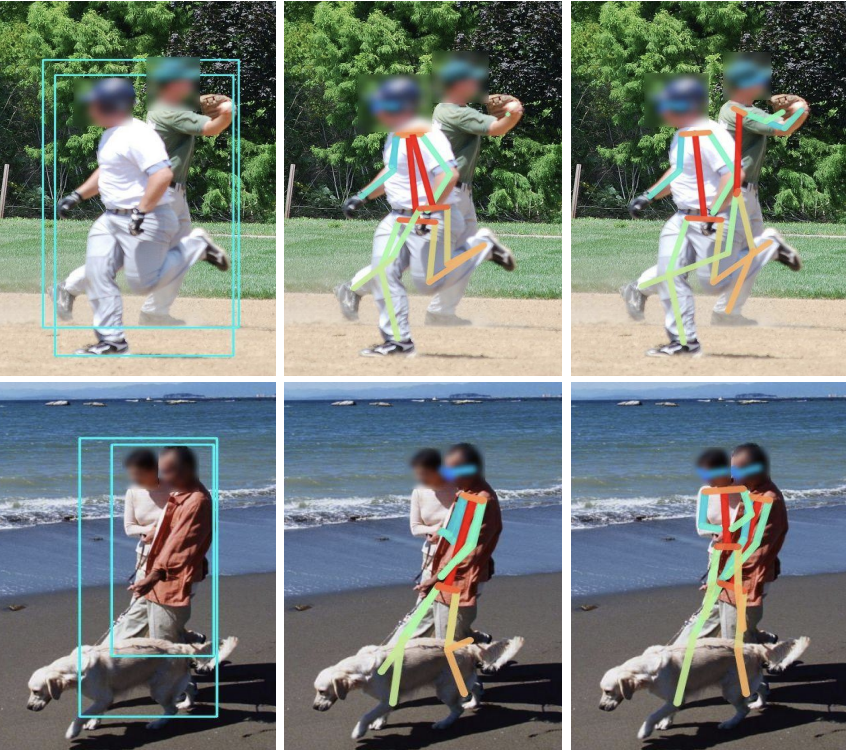
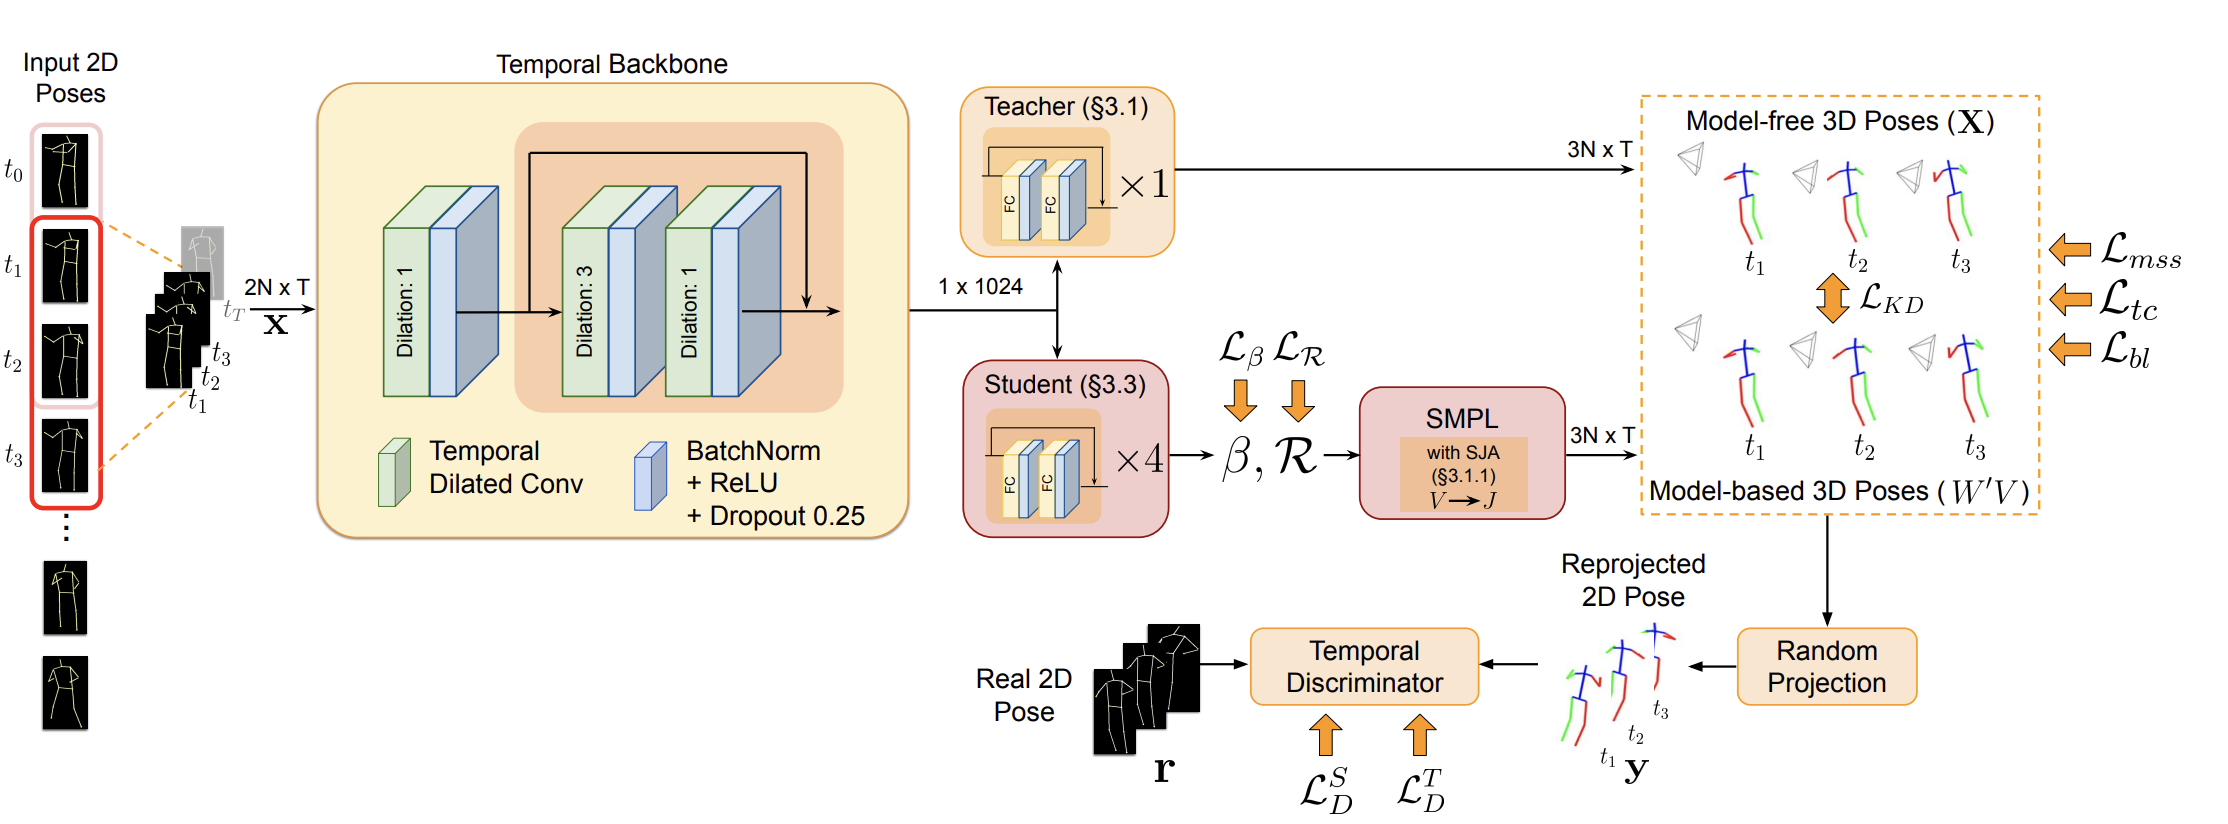
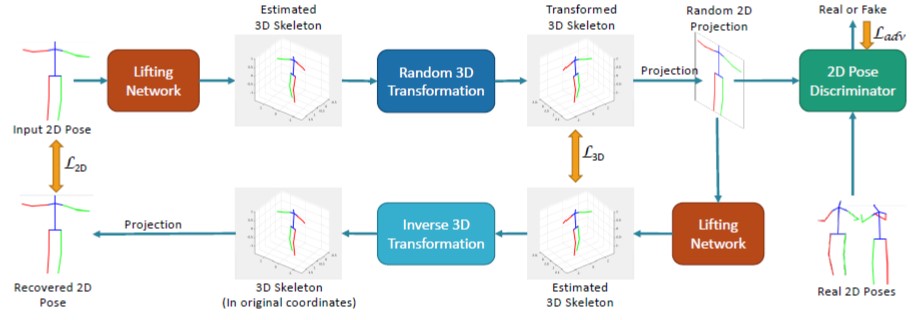
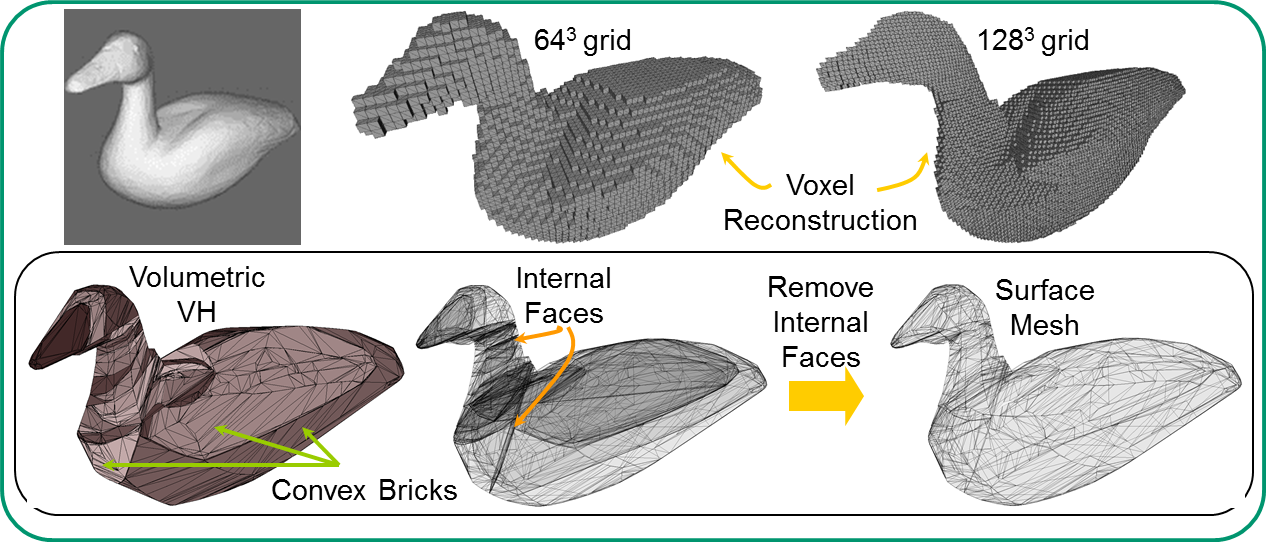
Work on 3D human pose and shape estimation, reconstruction from sparse views, geometric self-supervision, and pose estimation.
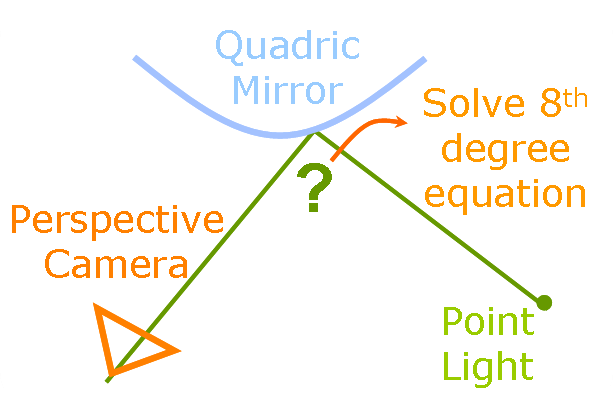
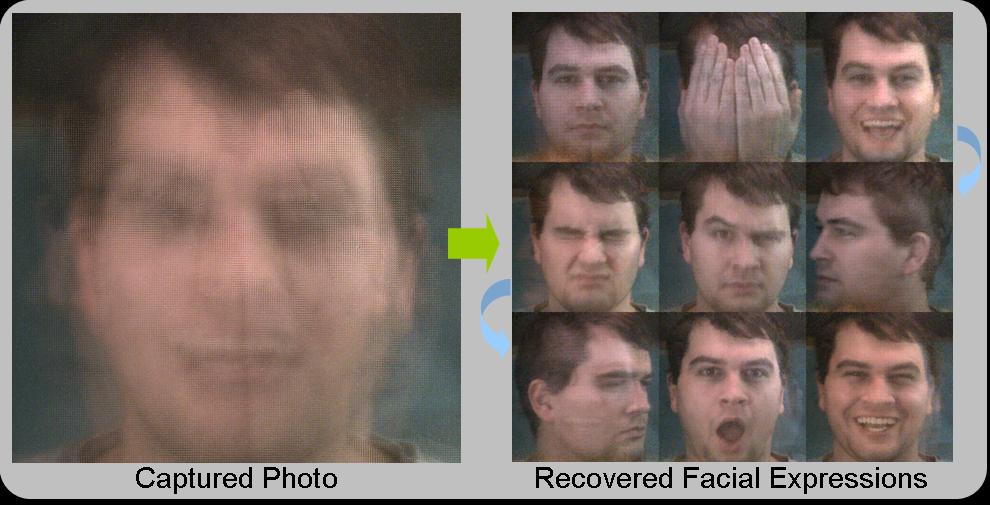
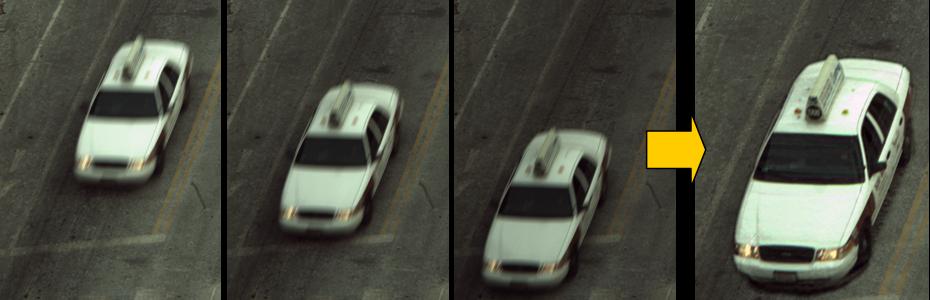
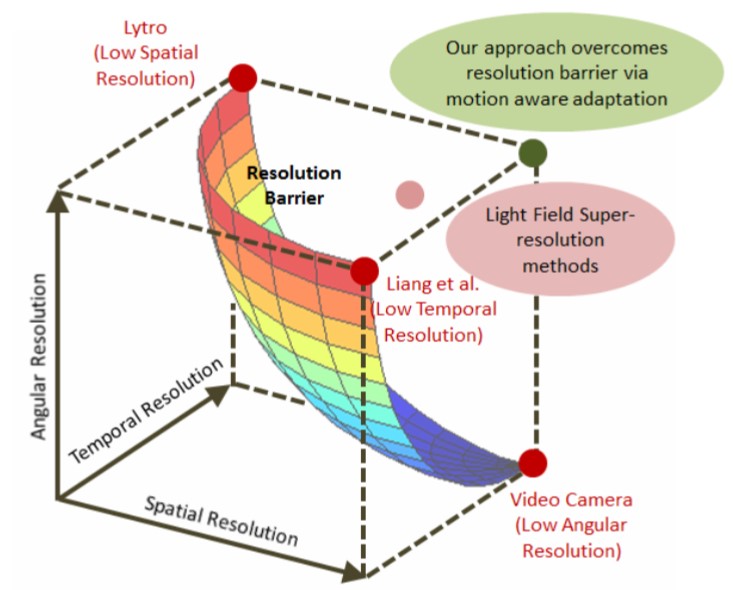
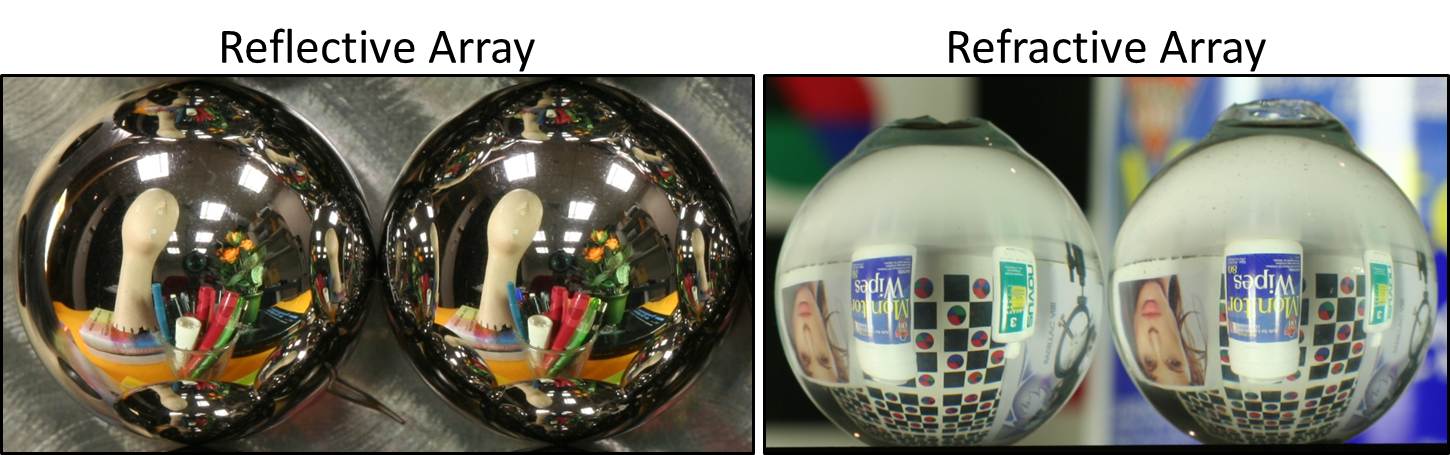
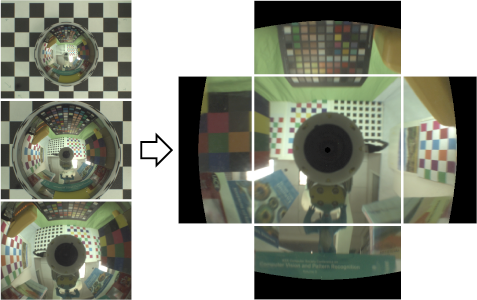
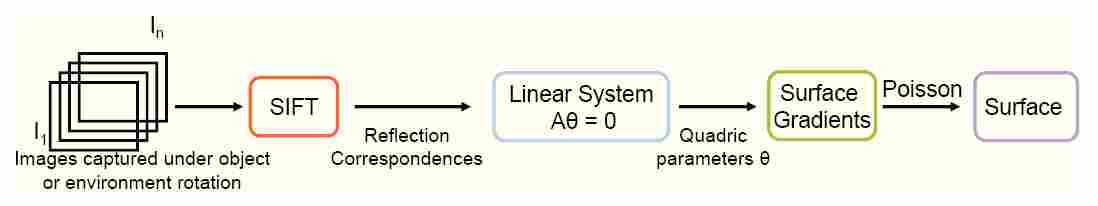
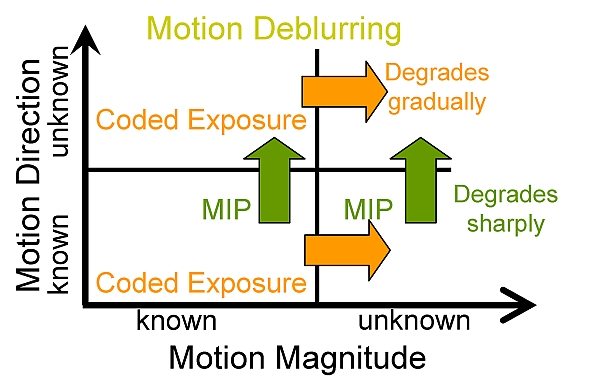
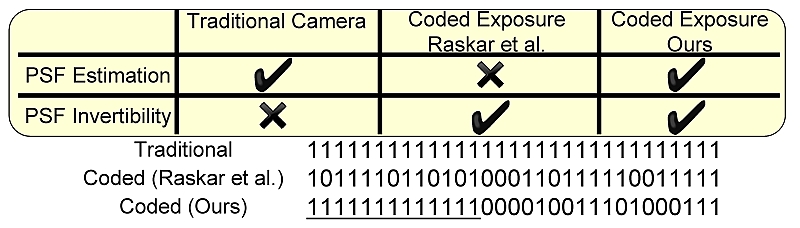
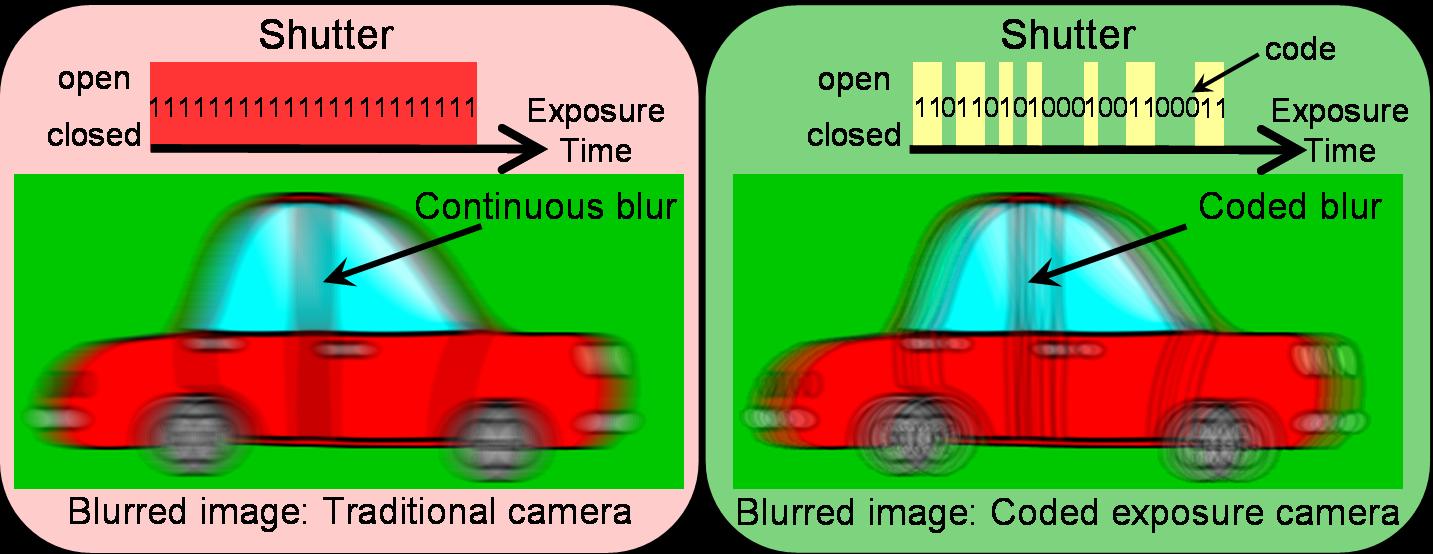
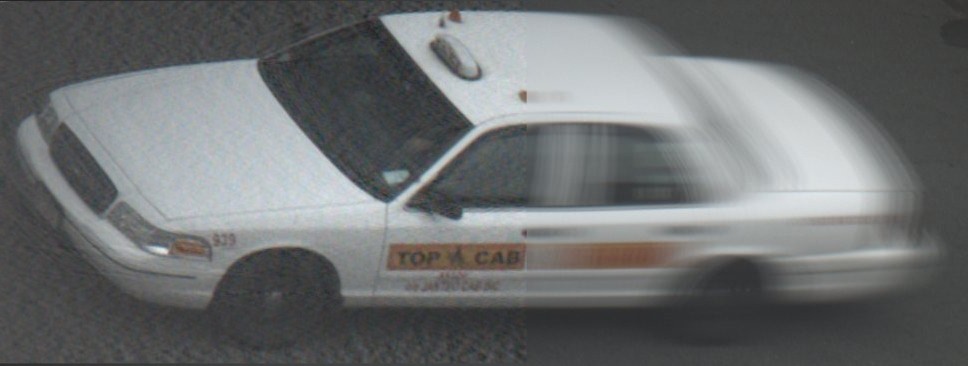
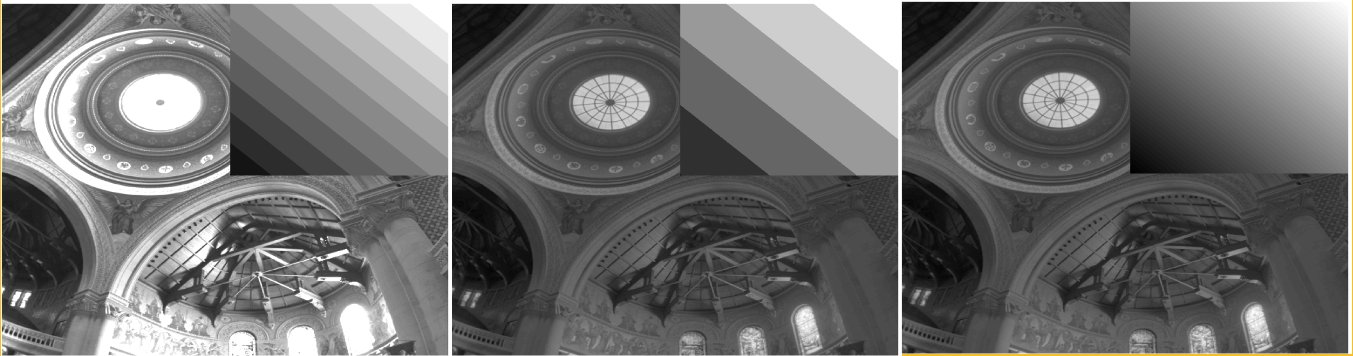
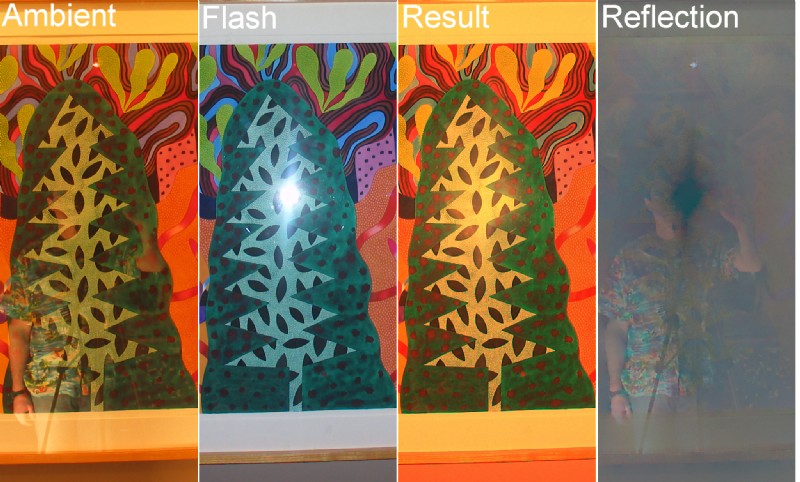
Computational photography, coded exposure, light fields, motion-aware imaging, camera calibration, and image formation.